New Google AI creates synthetic video of “unprecedented complexity”
One day AI's will be able to create photorealistic video content of anything and everything all by themselves, this is one step in that journey.

Key takeaways
- Uniquely, Transformers have attention, such that every output element is connected to every input element and the weightings between them are calculated dynamically.
- After a slice is generated, the padding in the video is replaced with the generated output and the process is repeated for the next slice.
Cite or link to this article
Griffin, M. (2019) 'New Google AI creates synthetic video of “unprecedented complexity”', 311 Institute, 10 June. Available at: https://www.311institute.com/new-google-ai-creates-synthetic-video-of-unprecedented-complexity/ (Accessed: 1 October 2026).
Recently Artificial Intelligence (AI) and so called Creative Machines have learned a whole host of new tricks when it comes to photorealistic synthetic video creation, including everything from being able to generate video from just a plain text description and realistic DeepFake full body and video content, through to being able to “predict the future” and create the video content that happened next after being shown just a single photo, for example in a bike race. And now, with respect to that latter breakthrough which happened last year, a team from Google has now published details of a new breakthrough Machine Learning system that can “Hallucinate clips,” in other words create the video content that would come in the middle of a sequence, by just being given a start and an end frame. And that’s something that even humans would struggle to do. Furthermore, while you'll likely look at the videos and think they're short and small, don't forget tech accelerates rapidly so tomorrow this tech will be dramatically improved and competing with your children for video creation jobs, and more.
The inherent randomness, complexity, and information denseness of videos naturally means that modelling realistic video clips at scale, and that last for a long period of time, remains something of a “grand challenge” for AI. But as developments like all of those mentioned above gather momentum and combine together it’s simply a question of when, not if, we get to the point where AI can produce full blown adverts and movies by itself, and that will be a revolution in content creation.
Despite these challenges though the team at Google Research say they’ve “made progress with novel networks that are able to produce diverse and surprisingly realistic frames” from open source video data sets at scale.
They describe their method in a newly published paper on the preprint server Arxiv.org “Scaling Autoregressive Video Models,” and on a webpage containing selected samples of the model’s outputs.
“[We] find that our [AI] models are capable of producing diverse and surprisingly realistic continuations on a subset of videos from Kinetics, a large scale action recognition dataset of videos exhibiting phenomena such as camera movement, complex object interactions, and diverse human movement,” wrote the coauthors. “To our knowledge, this is the first promising application of video-generation models to videos of this complexity.”
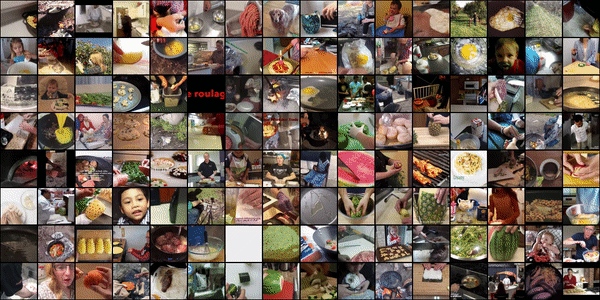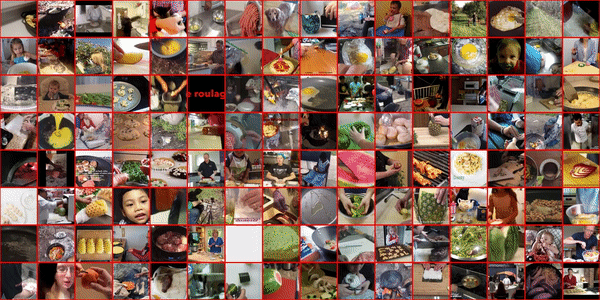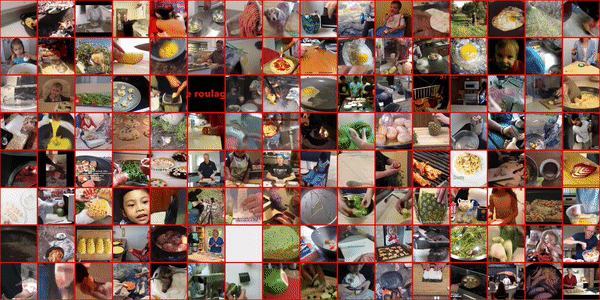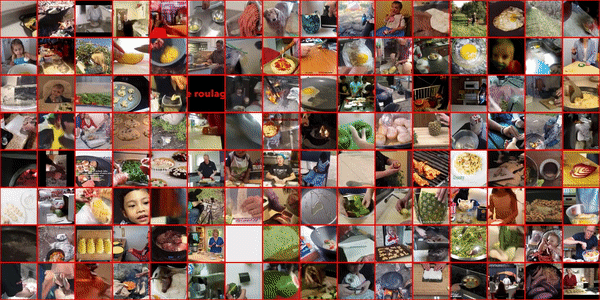 Video created from static images using the Kinetics data set
The researchers’ systems are auto-aggressive, meaning they generate videos pixel by pixel, and they’re built upon a “Generalization of Transformers,” a type of neural network architecture first introduced in a 2017 paper “Attention Is All You Need“ that was co-authored by scientists at Google Brain. As with all deep neural networks, Transformers contain neurons, or functions, that transmit “signals” from input data and slowly adjust the synaptic strength, or weights, of each connection, in much the same way the human brain does.
Uniquely, Transformers have attention, such that every output element is connected to every input element and the weightings between them are calculated dynamically. It’s this property that enables the video-generating systems to efficiently model clips as 3D volumes, rather than sequences of static 2D still frames, and “drives the direct interactions between representations of the videos’ pixels across dimensions.”
 Video created from static images using the BAIR data set
To maintain a manageable memory footprint and create an architecture suited to Tensor Processing Units, (TPUs), Google’s custom designed AI workload accelerator chipsets, the researchers combined the Transformer derived architecture with approaches that generate images as sequences of smaller, sub-scaled image slices. Their models then produced “slices,” which are sub-sampled lower-resolution videos, by processing partially masked video input data with an encoder, the output of which is used as conditioning for decoding the current video slice. After a slice is generated, the padding in the video is replaced with the generated output and the process is repeated for the next slice. And so on and so on until the system has created a video.
In experiments the team modelled slices of four frames by first feeding their AI systems video from the BAIR Robot Pushing robot data set, which consists of roughly 40,000 training videos and 256 test videos showing a robotic arm pushing and grasping objects in a box. Next they applied the models to down sampled videos from the Google DeepMind Kinetics-700 data set, a large scale action recognition corpus of data containing about 400,000 YouTube videos across 600 action classes, and their smaller models were trained for 300,000 steps, while larger ones were trained for 1 million steps. And the qualitative results were good.
The team reports seeing “highly encouraging” generated videos for limited subsets such as cooking videos, which they note feature camera movement and complex object interactions like steam and fire and which cover diverse subjects.
“This marks a departure from the often very narrow domains discussed in the video generation literature to date, such as artificially generated videos of moving digits or shapes,” wrote the researchers, “or videos depicting natural, yet highly constrained environments, such as robot arms interacting with a small number of different objects with a fixed camera angle and background.”
They concede that the models struggle with nuanced elements though, such as human motion and fingers and faces, but those failures will be solved in time, and those shortcomings aside, they claim “state-of-the-art results in video generation” and believe they “have demonstrated an aptitude for modelling clips of an unprecedented complexity.”
So while this is one big step for the creation of true synthetic video content creation in the future, it’s one big step in a very long journey. But that said, as more of these experiments come to light, and the more successful they become, the closer we’ll get to the day when the way we produce video will change forever, and when a system like this is combined with the aforementioned text to video system then that means we’ll all be able to produce our very own video clips, or movies, with nothing more than just a keyboard and a smartphone. And that will be awesome!
FAQ
Why does this matter?
One day AI's will be able to create photorealistic video content of anything and everything all by themselves, this is one step in that journey.

About the author
Matthew Griffin Founder, 311 Institute
Matthew Griffin is a multi-award winning Futurist and expert in Disruption and Innovation, Geopolitics, Leadership, and Technology, who NASA have described as a "walking encyclopaedia of the future" and a "futurist Polymath."
Read full bio
Matthew Griffin is a multi-award winning Futurist and expert in Disruption and Innovation, Geopolitics, Leadership, and Technology, who NASA have described as a "walking encyclopaedia of the future" and a "futurist Polymath." 15-time best selling author of the "Codex of the Future" series, Matthew is the Founder and Futurist in Chief of the 311 Institute, a global Futures and Deep Futures advisory firm working with royal households, world leaders, G7, G20, and G77 governments, NGOs, and multi-national mid and mega cap firms to help them explore, shape, and lead the next 50 years of business and society.
An award-winning YouTube creator with over a million followers, with an unrivalled global reach and impact, Matthew is a highly sought-after international keynote speaker, lecturer, and mentor who collaborates with global leaders through the United Nations Alliance of Civilizations (UNAOC) and United Nations General Assembly (UNGA) to shape pivotal initiatives such as the UN’s AI for Humanity program, the United Nations Conference of the Parties (UN COP), and the World Economic Forum in Davos.
As the former Global Head of Cloud, National Security, and Enterprise Sales for companies including Atos, Dell-EMC, and IBM, Matthew has a proven track record of building multi-billion dollar business units and turning failing divisions into market leaders. His ability to identify, analyse, and communicate the implications of hundreds of emerging technologies and trends is unparalleled, and his insights are trusted by many of the world’s most respected organisations, including ABB, Accenture, Adidas, AON, ARM, BCG, Centrica, Citi, Coca-Cola, Dentons, Deloitte, Dow Jones, EY, Google, KPMG, Lego, Legal & General, LinkedIn, Microsoft, PepsiCo, Qualcomm, RWE, Samsung, Siemens AG and Siemens Energy, T-Mobile, UBS, VISA, Walmart, Workday, Worldpay and many others.
Regularly featured in the global media including the AP, BBC, Bloomberg, CNBC, Discovery, Forbes, Khaleej Times, Telegraph, TIME, ViacomCBS, WIRED, and the WSJ, Matthews mission is to help organisations create a fair and sustainable future whose benefits are shared by everyone irrespective of their ability, background, or circumstances.
What future do you need to see?
Choose one to get started on AI and intelligence and the future of your organisation.
Sources and further reading
- Googles ai can create videos from start and end frames alone venturebeat.com
- Scaling Autoregressive Video Models arxiv.org
- Attention Is All You Need arxiv.org
- BAIR Robot Pushing robot data set people.eecs.berkeley.edu
- Kinetics-700 data set deepmind.com
Source: first published by the 311 Institute on 10 June 2019. Cite as: Griffin, M. (2019). New Google AI creates synthetic video of “unprecedented complexity”. 311 Institute. https://www.311institute.com/new-google-ai-creates-synthetic-video-of-unprecedented-complexity/
You are welcome to quote this article with credit and a link to the original.